Ditch the guesswork with your RAG retrieval setup
StratRAG is a tool for systematic improvement of RAG retrieval performance for AI/ML engineers, Software engineers, and agencies who build reliable RAG systems at scale, not just demo applications.
Request a demo
Chat with our founders to explore your use case
Picture this…
You have worked on a RAG system for months, and all fifteen examples you could think of passed every time. You are patiently waiting for your boss’s boss to approve your work. An exciting demo is prepared. All of a sudden, the high-ranking manager asks a random question that you are sure your system will easily answer.
But… it chokes?!
You are embarrassed, your manager is embarrassed, and the funding is gone. YOU are the one responsible. Apparently, the retriever couldn’t find the exact document. The very smart generator model, even with its gigantic prompt, couldn’t hallucinate anything remotely in the right direction…
The result was abysmal?!
You are not alone; more than 95% of AI projects never reach production. We can safely assume many of them are more “reliable” due to their RAG components. Now, you were lucky, as the failure was internal. There are many high-profile cases of lawyers citing imaginary cases or of companies with mediocre customer support due to bad RAG implementation. In an extreme case, a Canadian airline had to pay a customer for a perk its ungrounded chatbot hallucinated.
But what if…
You can build a RAG system much like you would build a to-do app: the scope is clear, the logic is explicit, and the behavior can be covered by comprehensive tests. In most cases, it will retrieve the right source, and when it does not, the failure mode is usually identifiable, which means you can add rules and guardrails to mitigate it—just as a to-do app prevents empty tasks from being added.
Enter StratRAG
The RAG retrieval optimization tool that doesn’t make you want to pull your hair out.
We built this specifically for engineers tasked with RAG systems development and maintenance who are tired of randomly trying new approaches without any systematic way of assessing their performance. Need precision and recall evaluation? Got it. Synthetic data to assess a model’s domain competence? Of course. A way to check if the combination of chunking, embedding, reranking, and keyword matching fits well together? Done.
No more ineffective huge prompts to handle 100s of “corner cases”. No more explaining why an intuitive RAG setup simply doesn’t work. No more tolerating retrieval that nearly works but still leaves the RAG dependent on the generator model’s training data.
Just systematic RAG retrieval strategy optimization that gets you to the right setup for your particular situation, on time and on budget.
Explore various retrieval strategies, ensuring you choose the right one
You shouldn’t need a crystal bulb to get a functioning retrieval. We built an easy experimentation interface to row several experiments in parallel.
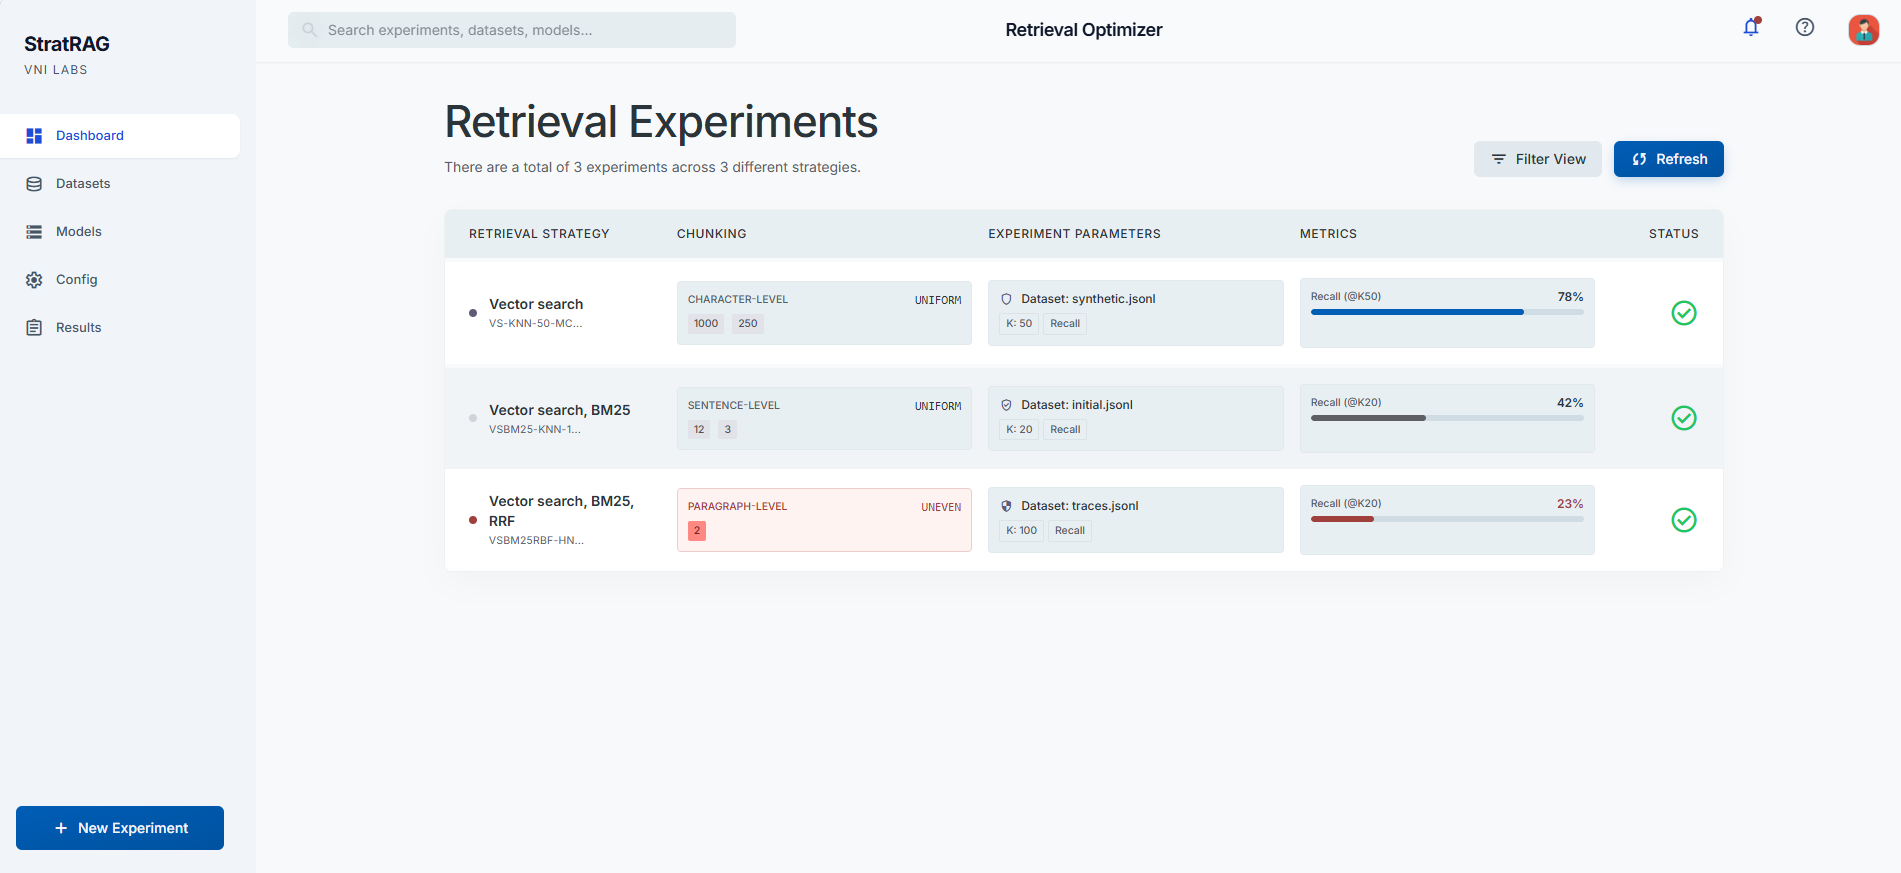
High-level view of performed experiments and their results. Duplicate, modify, rerun, or export parameters when the result is satisfactory.
Seemless integration with your data
Import your knowledge base, production traces and other data to StratRAG. Then choose between manually creating a golden dataset in a convenient interface or using synthetic data generation with seamless human-in-the-loop integration.
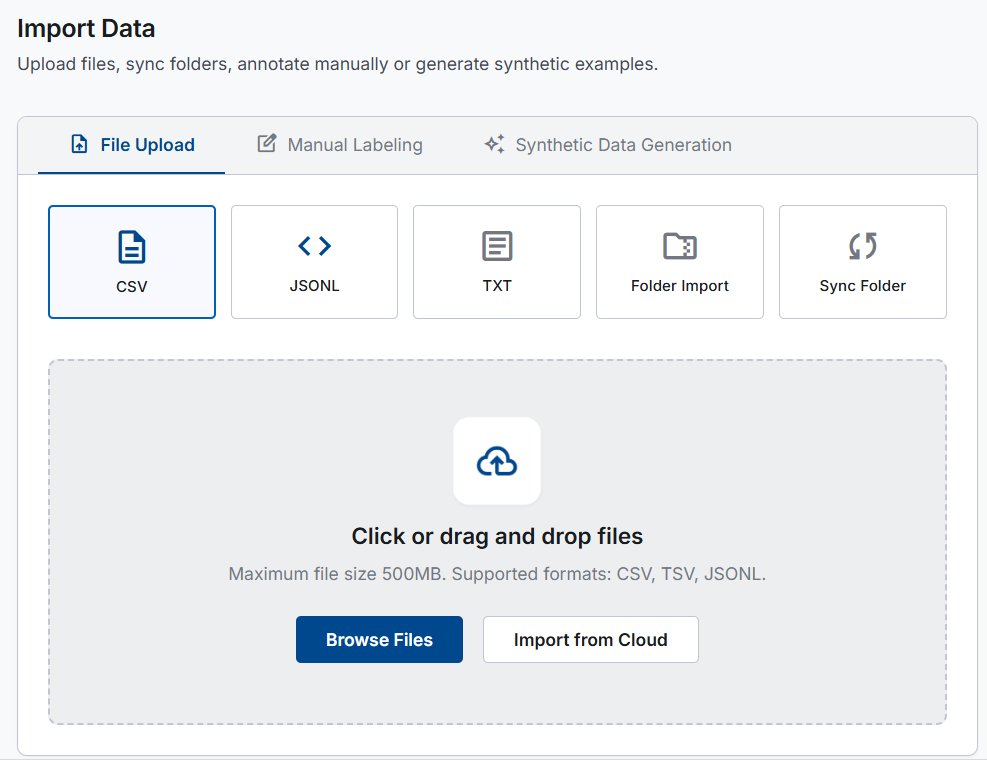
Import or synchronize from local or cloud directory, file by file or entire folders.
Sound interesting?
StratRAG is rolling out to selected AI practitioners. Have a chat with our founders and see if we are a good fit for you!
Request a demo